

Kimi K3: The Largest Open-Weight AI Model Ever, and What It Means for AI Agencies
Moonshot AI's 2.8-trillion-parameter Kimi K3 rivals Claude and GPT on coding tasks. Here's what its open weights mean for AI builders.
On July 27, Beijing-based Moonshot AI released the full weights for Kimi K3 — and by most measures, it's the largest open-weight language model anyone has ever shipped. At roughly 2.8 trillion parameters, with a 1-million-token context window and frontier-level coding scores, K3 isn't a research curiosity. It's a model agencies and automation builders can actually download, self-host, and put into production today. For a HadidizFlow audience built around AI-driven automation and no-code delivery, that's worth understanding in detail.
Kimi K3 is a mixture-of-experts model built on a new architecture Moonshot calls Kimi Delta Attention (KDA) combined with Attention Residuals, running across 93 layers (69 KDA layers plus 24 gated MLA layers) inside what the company calls a "Stable LatentMoE" framework. Only 16 of 896 experts activate per token — about 104 billion active parameters out of the 2.8 trillion total — which is what makes a model this large practical to run at all. Moonshot says the design delivers roughly a 2.5x improvement in scaling efficiency over its predecessor, Kimi K2.
The model also ships with an always-on "thinking mode" for reasoning tasks and native visual understanding, putting it in the same category as the frontier closed models rather than the smaller open models that came before it.
The reception has been unusually fast. On Hugging Face, Kimi K3 hit the #1 spot on the trending chart within 30 minutes of release — the fastest climb the platform had recorded — and had roughly 7,700 likes and tens of thousands of downloads by the next day. Coverage from Bloomberg, VentureBeat, Fortune, and Fast Company all framed it the same way: a Chinese lab shipping a genuinely frontier-class model as open weights, not just a benchmark chart.
The numbers back that up. On the Artificial Analysis Intelligence Index, K3 scores 57.11, landing 4th overall behind Claude Fable 5 and GPT-5.6 Sol, and just ahead of Claude Opus 4.8. Coding is where it stands out: K3 took the #1 spot on LMArena's Frontend Code Arena with a 1,679 Elo score, ahead of both Claude Fable 5 and GPT-5.6 Sol. On the Coding Agent Index, it matches GPT-5.6 Terra and GPT-5.5. For a team pricing out which model to route agentic coding tasks to, that combination of near-frontier general intelligence, class-leading coding scores, and open weights is new.
"Open weights" doesn't mean unrestricted here, and agencies evaluating K3 for client work should read the license before assuming otherwise. Moonshot's Kimi K3 License is a bespoke agreement: research, internal use, and most commercial embeds are wide open, but running K3 as a paid API or Model-as-a-Service above roughly $20 million in annual revenue triggers a requirement to sign a separate agreement with Moonshot. There's also a user-interface attribution requirement once a deployment crosses 100 million monthly active users. For the overwhelming majority of agencies and automation builders, neither threshold is close — but it's worth knowing the ceiling exists before building a resale offering on top of it.
Three things make K3 relevant beyond the headline numbers. First, cost: an open-weight model that trades blows with Claude and GPT on coding and agentic benchmarks gives teams a genuine self-hosted alternative for high-volume workloads, rather than a fallback that trails frontier models by a wide margin. Second, data sovereignty: clients in regulated industries who won't let code or documents leave their infrastructure now have a frontier-tier option that can run on-prem or in a private cloud via vLLM and similar serving stacks. Third, the ecosystem is moving fast around it — the Kimi Delta Attention kernel (FlashKDA) was already climbing GitHub's trending page within days of the weights landing, a sign that tooling support is catching up quickly rather than lagging for months.
None of that makes K3 a drop-in replacement for Claude or GPT in every workflow — it still trails on general intelligence benchmarks, and self-hosting a 2.8-trillion-parameter model is a real infrastructure commitment, not a checkbox. But as a signal of where open-weight models now sit relative to closed frontier systems, K3 is the clearest data point yet.
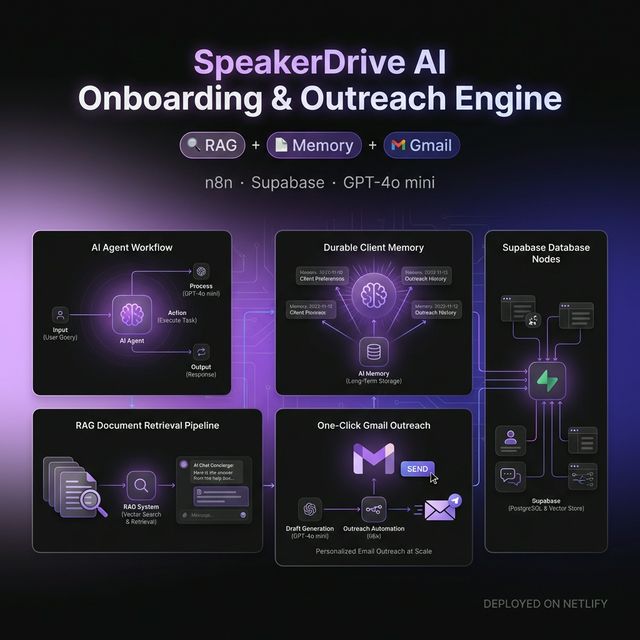
RAG assistants on your documents, AI agents that act in your tools, and LLM features inside your product.
Our cutting-edge features simplify collaboration and creativity, making your workflow intuitive and efficient. Transform your vision into reality effortlessly with Hadidiz Flow.